
The source and why it matters
This review examines "Ethics and security in artificial intelligence and machine learning: Current perspectives in computing", an article in the open-access journal INJOSER. The article reports no new data. Instead, it gathers published work on the ethical and security problems that AI and machine learning systems create in fields such as healthcare, finance, education and cybersecurity.
The pairing of ethics and security is worth taking seriously, because the two concerns increasingly collide. When a model reveals information about the people in its training data, that is a security breach and a privacy harm at once. When crafted inputs can steer a system, nobody can rely on it to treat people fairly. Bertino et al. (2021) capture this two-way link with the phrase "AI for security and security for AI". Doctoral researchers in computing often have to cover both themes in a literature review, a proposal or an ethics section, which makes the construction of a review like this one worth studying closely.
What the article covers
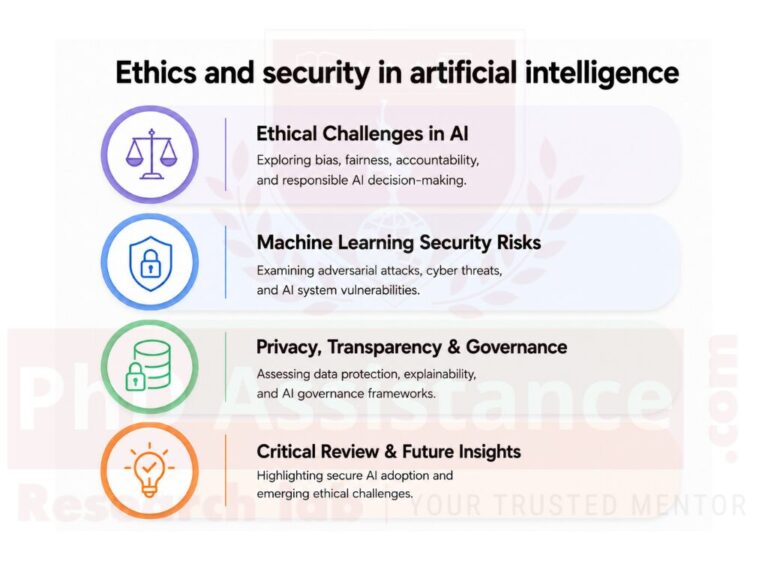
According to the earlier review of it, the article is arranged around two clusters of issues. The ethical cluster covers algorithmic bias and discrimination, the opacity of model decisions, and threats to privacy. The security cluster covers adversarial attacks, data manipulation and the misuse of generative techniques such as deepfakes. Among its sources are the overview of AI ethics by Huang et al. (2022), the account of AI and security by Bertino et al. (2021), and the discussion of AI security in future 6G networks by Siriwardhana et al. (2021).
The article concludes that responsible AI needs several things working together: regulation, transparent algorithms, effective security measures and cooperation among developers, users and regulators. Fairness, accountability and transparency serve as its organising values.
How far those conclusions can be trusted depends on method. The article is a narrative review, meaning that it synthesises a selection of the literature without saying how sources were searched for, chosen or appraised. Narrative reviews are a recognised and legitimate genre and work well as an introduction to a field. They cannot, however, make the same claims as systematic or scoping reviews (Grant & Booth, 2009).
Strengths
- Breadth. Covering ethics and security in one piece lets readers notice overlaps that a specialist review of either area might miss.
- Cross-sector framing. Examples drawn from health, finance, education and cybersecurity show the same risks recurring in settings where the stakes differ.
- Accessible synthesis. A newcomer can use an overview like this to locate the main themes and the authors who shaped them.
- A practical conclusion. The call to combine regulation, transparency and security engineering fits the direction that policy has since taken.
Limitations and methodological issues
Search and selection are not reported
No search strategy, inclusion criteria or source appraisal is given, so a reader cannot judge whether the literature discussed is representative or was chosen to suit the argument. Computing already has established guidance for systematic reviews (Kitchenham & Charters, 2007), and PRISMA 2020 lists what a transparent review should report (Page et al., 2021). A narrative review does not have to meet these standards in full. Even a brief note on databases, date ranges and selection principles, though, would let readers weigh its claims.
Problems receive more space than solutions
Concrete work on mitigation is plentiful. Differential privacy sets formal limits on what a model can reveal about any individual (Dwork & Roth, 2014). Studies of membership inference measure how much trained models leak (Nasr et al., 2019). Datasheets document how training data were gathered and what uses they suit (Gebru et al., 2021). For high-stakes decisions, an interpretable model may serve better than a black box explained after the event (Rudin, 2019). Newer work, discussed below, adds systematic catalogues of attacks and defences that make this gap easier to close (Vassilev et al., 2025; Gallegos et al., 2024).
Principles without the debate about principles
The article appeals to fairness, accountability and transparency but does not engage with research on AI ethics principles as such. Jobin et al. (2019) analysed 84 ethics guidelines and found convergence on a small set of principles, chiefly transparency, justice and fairness, non-maleficence, responsibility and privacy, alongside disagreement over how to interpret and apply them. Mittelstadt (2019) argued that principles cannot guarantee ethical AI on their own, because AI development lacks the shared aims, professional norms, proven methods and accountability mechanisms that give principles force in medicine. Any review that recommends principle-based governance needs to answer this objection, and auditing research now offers one way to do so (Laine et al., 2024).
Evidence for harms is general rather than specific
A claim about bias carries more weight when it rests on a documented case. Obermeyer et al. (2019) showed that a widely used healthcare algorithm, which treated health costs as a stand-in for health needs, gave Black patients the same risk scores as white patients who were less ill. The case shows that bias can enter through the choice of target variable and not only through the data, and drawing out mechanisms of this kind is what a review should do.
Ethics and security sit side by side rather than together
Treating ethics and security in a single review is the article's most promising move, and also where it stops short. The two sets of issues run largely in parallel. An integrated analysis would look for the points of contact: an attack on training data that produces unfair outcomes, privacy protections that cost accuracy for small groups, or transparency demands that expose a model to attack. Design decisions are hardest at these trade-offs, and a review adds most value there, because neither the ethics literature nor the security literature settles them alone.
Several sources, finally, are forward-looking position papers or short conference contributions, such as the discussion of AI security in 6G networks (Siriwardhana et al., 2021). These help to flag emerging concerns, but they describe anticipated rather than observed risks, and a review should make that distinction visible.
How the article sits in the wider literature
Regulation has moved fast since many of the article's sources appeared. The EU Artificial Intelligence Act follows a risk-based model: it bans some practices, sets requirements for high-risk systems that include accuracy, robustness and cybersecurity, and imposes transparency duties for certain generated content (European Parliament & Council of the European Union, 2024). A current review would test its recommendations against this framework instead of calling for regulation in general terms.
The security literature also contains a methodological strand that a review could put to use. Arp et al. (2022) identified recurring pitfalls in machine learning for computer security research, among them sampling bias, data snooping and inappropriate baselines, each of which can make reported results look stronger than they are. For a doctoral researcher these pitfalls matter as much as the threats, because they set how much confidence the evidence deserves.
| Concern | Example of the risk | Examples of safeguards | Key source |
|---|---|---|---|
| Bias and discrimination | Proxy target that disadvantages a group | Audit target variables; test outcomes across groups | (Obermeyer et al., 2019) |
| Opacity | High-stakes decisions from models no one can explain | Prefer interpretable models where stakes are high | (Rudin, 2019) |
| Privacy leakage | Membership inference against trained models | Differential privacy; restricted model access | (Nasr et al., 2019; Dwork & Roth, 2014) |
| Undocumented data | Models used outside the conditions their data reflect | Datasheets describing collection and limits | (Gebru et al., 2021) |
| Weak evaluation | Security results inflated by data snooping or sampling bias | Realistic splits, baselines and threat models | (Arp et al., 2022) |
| Governance | Principles not translated into practice | Risk-based legal obligations; accountability mechanisms | (European Parliament & Council of the European Union, 2024; Mittelstadt, 2019) |
What newer research adds (2024 to 2026)
Work published since 2024 changes the picture in three ways. Large language models have become the main object of study, security research now has shared taxonomies, and governance research has moved from listing principles to asking how they can be audited. The table summarises verified studies and reports that bear on the reviewed article.
| Study | Design and data | Key finding | What it means for the reviewed paper |
|---|---|---|---|
| Carlini et al. (2024) | Attack study on web-scale image-text training datasets | Two practical poisoning attacks, one exploiting web content that changes between curation and download, one exploiting timed edits to crowd-sourced sources; 0.01% of LAION-400M or COYO-700M could have been poisoned for about USD 60 | Data manipulation is a present, low-cost threat, so a review should treat data provenance as a core safeguard |
| Vassilev et al. (2025) | Official taxonomy built from a survey of the adversarial machine learning literature | Classifies attacks on predictive and generative AI by attacker goals (availability, integrity, privacy), capabilities, knowledge and lifecycle stage, with matching mitigations and open challenges | Offers a ready structure for the security half of a review, replacing ad hoc lists of threats |
| Gallegos et al. (2024) | Survey of bias evaluation and mitigation for large language models | Three taxonomies: metrics by the level at which they operate, datasets as counterfactual inputs or prompts, and mitigation by stage from pre-processing to post-processing | Bias in generative models needs its own measures; general fairness language is no longer enough |
| Das et al. (2025) | Survey of security and privacy challenges of large language models | Reviews jailbreaking, data poisoning and leakage of personally identifiable information, risks in domains such as education and healthcare, and defences | Confirms the security-privacy overlap the paper gestures at, now for the systems most people use |
| Laine et al. (2024) | Systematic literature review of 93 studies on ethics-based AI auditing | Fairness was the most discussed principle (84 studies), then transparency (54), non-maleficence (41) and responsibility (39); most work is social and process-oriented | Auditing is one route from principles to practice that the paper does not discuss |
| Bengio et al. (2024) | Policy Forum by 20 researchers in Science | Argues that preparing for risks from advanced AI requires technical research and development as well as adaptive, proactive governance | Supports the call for combined technical and regulatory action, while raising the stakes |
| Bengio (2025) | International report by 96 experts, backed by 30 countries, the UN, EU and OECD | Finds that the best available risk-management techniques still have highly significant limitations and offer no quantitative guarantees; current interpretability methods remain severely limited | Cautions against any review that presents safeguards as a solved problem |
Much of this work confirms the article's starting point. The overlap between ethics and security is now well documented: surveys of large language models place privacy leakage and data poisoning beside jailbreaking as linked failures (Das et al., 2025), and poisoning research shows that the integrity of training data, which shapes both fairness and safety, can be undermined by outsiders at modest cost (Carlini et al., 2024). The article's closing call for regulation and security engineering together is also echoed by senior researchers (Bengio et al., 2024).
Other findings challenge the article, or at least its level of detail. The NIST taxonomy shows that the security literature is mature enough to be organised systematically, so a review that lists threats without a framework now looks dated (Vassilev et al., 2025). Research on bias in language models has developed its own metrics and mitigation stages (Gallegos et al., 2024), which means general appeals to fairness no longer reflect the field. The international safety report, meanwhile, warns that safeguards remain partial (Bengio, 2025), a caution that sits awkwardly with confident recommendations.
Several questions are still open. Auditing research has grown, yet it concentrates on social and process aspects and says less about technical verification (Laine et al., 2024). Evidence on how well defences hold up in deployed systems is thin, and the trade-offs between fairness, privacy and robustness that the article leaves unexamined are still under-studied. These are promising areas for doctoral work.
What it means for doctoral researchers
A broad narrative review is a good place to start reading, but a doctoral literature review must go further. Pick the review type that fits your purpose (Grant & Booth, 2009): a scoping review to map a wide field, a systematic review to answer a focused question, or a critical review to build a conceptual argument. Report how you searched for and selected sources even when the review is not fully systematic, and narrow the scope until you can examine mechanisms and safeguards in depth.
The newer literature also gives you ready-made structure. You can organise security threats with the NIST taxonomy (Vassilev et al., 2025), bias in language models with the categories of Gallegos et al. (2024), and governance with the auditing literature (Laine et al., 2024). Because these frameworks are already in use, adopting one makes your review easier to compare with others and shows examiners that you know the current state of the field. Check the date coverage of every review you rely on, since anything written before 2024 will miss most work on large language models.
Whatever review you read in this area, this one included, a short set of questions helps you decide how much weight it deserves. How were the sources found and chosen? Are harms backed by documented cases, or simply asserted? Are safeguards described together with evidence of how well they work? Is the regulatory discussion current? And does the review explain where ethical and security goals conflict?
Worked example (illustrative)
Consider a doctoral researcher interested in "AI ethics and security in healthcare" who starts from a narrative review like this one. She narrows the topic to privacy attacks on clinical prediction models and frames a focused question: which defences have been evaluated on real clinical data? She searches named databases with a recorded search string and date, classifies each study's threat model with the NIST taxonomy (Vassilev et al., 2025), screens studies against stated criteria, and notes evaluation pitfalls of the kind described by Arp et al. (2022). She then maps the defences she finds to the relevant legal requirements. Her gap is specific: few defences have been tested on clinical data under realistic threat models. The example is hypothetical, but it shows how a broad overview turns into a researchable question; see also research gap identification.
Common mistakes in literature reviews on AI ethics and security
- Listing risks such as bias, privacy and adversarial attacks without explaining the mechanisms behind them.
- Citing ethics principles without discussing how, or whether, they are put into practice.
- Leaving out how sources were found and selected, so the review cannot be assessed or updated.
- Treating regulation generically instead of engaging with specific, current legal frameworks.
- Accepting reported security results without checking how the evaluation was designed.
- Relying on reviews written before 2024 and so overlooking work on large language models.
- Covering so many sectors and threats that no single issue is analysed in depth.
Key takeaways
- The reviewed article gives a broad narrative overview of ethical and security challenges in AI and machine learning.
- Its main weaknesses are an unreported search and selection process and thin treatment of concrete safeguards (Grant & Booth, 2009; Page et al., 2021).
- Ethics and security overlap: privacy attacks, biased targets and cheap data poisoning show how technical design produces ethical harm (Nasr et al., 2019; Obermeyer et al., 2019; Carlini et al., 2024).
- Research since 2024 supplies shared taxonomies for attacks and for bias in language models, which a current review should use (Vassilev et al., 2025; Gallegos et al., 2024).
- Principles converge but are hard to apply, and safeguards remain partial, so reviews should engage with auditing, regulation and their limits (Mittelstadt, 2019; Laine et al., 2024; European Parliament & Council of the European Union, 2024; Bengio, 2025).
- A doctoral review should narrow its scope, state its method and link each risk to safeguards with evidence of how well they work.