
What XAI is, and why finding a problem is hard
Explainable artificial intelligence (XAI) develops methods that help people understand why a machine learning model produces a given output. Some methods build models that are interpretable by design, such as sparse linear models or short decision rules. Others explain a trained model after the fact: LIME fits a simple local surrogate around one prediction (Ribeiro et al., 2016), and SHAP attributes a prediction to input features using Shapley values from cooperative game theory (Lundberg & Lee, 2017), with fast exact versions for tree ensembles (Lundberg et al., 2020).
The field is now large. One survey screened 410 articles published between January 2016 and October 2022 and organised them along four axes: explaining the data, explaining the model, post-hoc explanation and the assessment of explanations (Ali et al., 2023). For a doctoral researcher, that volume is both an opportunity and a trap. Many papers apply an existing explanation method to a new data set and report attractive plots, and it is easy to propose one more. Examiners will ask what problem such a study solves. The steps below are designed to help you answer that question before you start.
Regulation has also raised the stakes. The EU Artificial Intelligence Act requires high-risk AI systems to be transparent enough for deployers to interpret their output and use it appropriately, and gives affected persons a right to an explanation of certain individual decisions (European Parliament & Council of the European Union, 2024). What counts as an adequate explanation in law and in practice is itself an open research question.
Step 1: Move from gap-spotting to problematisation
Most research questions are built by gap-spotting: finding a method, data set or population that the literature has not yet covered. Sandberg and Alvesson (2011) show that this habit tends to produce incremental studies that reinforce existing assumptions. Problematisation goes further: it identifies an assumption that a body of work takes for granted and asks what happens if it is wrong (Alvesson & Sandberg, 2011).
XAI has several assumptions worth challenging. One is that post-hoc explanations are faithful to the model they describe. Rudin (2019) argues that for high-stakes decisions this cannot be assumed, and that inherently interpretable models should be preferred where they perform comparably. Another is that interpretability must cost accuracy: the survey by Ali et al. (2023) found no scientific evidence for a general trade-off. A third is that a good explanation is one that looks plausible to its designer, rather than one that helps a defined user make a better decision. A problem built on testing one of these assumptions is stronger than one built on applying SHAP to a new data set.
Step 2: Survey the ten open problem areas
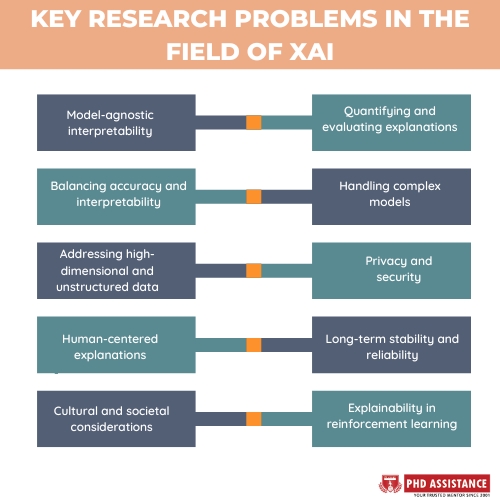
The ten problem areas below are a useful map, provided each is narrowed to a question one thesis can answer. The table restates each as an example question with a typical design; the questions are illustrations, not ready-made topics.
| Problem area | What is unresolved | Example doctoral question | Typical design |
|---|---|---|---|
| Model-agnostic methods | Whether one method explains many model types equally well | Do LIME and SHAP attributions agree across gradient-boosted trees and neural networks trained on the same tabular task? | Controlled comparison on benchmark data; agreement and faithfulness metrics |
| Evaluating explanations | No agreed metrics or ground truth for explanation quality | Can synthetic data with known causal features serve as ground truth for ranking attribution methods? | Synthetic benchmarks plus functional metrics such as deletion tests |
| Accuracy and interpretability | Whether a trade-off exists in a given domain | Does a sparse interpretable model match a black-box model's accuracy on a clinical risk task? | Benchmarking with cross-validation and calibration |
| Complex models | Explaining very large models with many parameters | How stable are feature attributions for a deep image classifier under small input perturbations? | Robustness experiments; stability metrics |
| High-dimensional and unstructured data | Explanations for images, text and sensor streams | Which explanation formats help analysts interpret a time-series fault classifier? | Method comparison plus small expert study |
| Privacy and security | Whether explanations leak information or can be manipulated | Does releasing feature attributions increase the success of membership inference against a model? | Attack experiments under a stated threat model |
| Human-centred explanations | Matching explanations to users' needs and decisions | Do counterfactual or attribution explanations lead loan officers to better override decisions? | Randomised user study on a realistic task |
| Stability under drift | Explanations that change as data shift over time | How do SHAP attributions for a fraud model change under concept drift, and can that change signal drift early? | Longitudinal analysis of production-like data streams |
| Cultural and societal factors | Whether explanation needs differ across groups and contexts | Do patients in two health systems differ in what explanation of an AI triage result they find acceptable? | Qualitative interviews or survey experiment |
| Reinforcement learning | Explaining sequential decisions and policies | Can summaries of key states help users predict a trained agent's behaviour in new situations? | Simulation environment plus user prediction task |
Step 3: Put evaluation at the centre
Whatever area you choose, evaluation will be part of the problem. Ali et al. (2023) list XAI system design, generalisation of methods, user interaction, ground-truth evaluation and better tools among the open issues, and they group assessment of explanations into human-centred, application-grounded and functionally grounded approaches. Functionally grounded tests use computational proxies such as fidelity (does the explanation reflect what the model does?) and stability (does a small change in input produce a small change in explanation?). Human-centred and application-grounded tests involve people doing real tasks, and they answer a different question: does the explanation help?
A strong thesis usually combines both. A method that scores well on fidelity but confuses its users has not solved a practical problem, and a user study of an unfaithful explanation measures persuasion rather than understanding. Evaluation also depends on the field. Domain surveys catalogue the techniques used in areas such as healthcare (Chaddad et al., 2023), and Bank of England researchers have applied explanation methods to a default-risk model (Bracke et al., 2019); read the work in your target domain to learn who the users are and what decisions the explanations must support.
Step 4: Consider security, privacy and social context
Explanations reveal information about a model, and that can matter for security. Adversarial machine learning research catalogues evasion, poisoning and privacy attacks against models (Vassilev et al., 2025). Whether, and how far, releasing explanations changes exposure to such attacks is a researchable question, but it needs a clear threat model and responsible handling of any attack you demonstrate.
Social context matters too. Agreeing on principles such as transparency does not settle what an explanation should contain or who it should serve, and principles alone cannot guarantee ethical practice (Mittelstadt, 2019). Problems about who needs which explanation, in which setting, often call for qualitative or mixed methods, and they are as legitimate as algorithmic ones.
Worked example: from interest to problem statement (illustrative)
A doctoral researcher is interested in "XAI for credit scoring". That is an area, not a problem. The steps below show how it can be narrowed; the example is hypothetical.
- Area. Explanations for machine learning credit models.
- Gap-spotting version. "No study has applied SHAP to credit data from my country." This is a gap, but filling it would mainly reproduce known methods.
- Assumption found. Studies often present SHAP attributions as the reasons for a decision, assuming that they are stable. If small changes in training data or random seeds change the top-ranked features, the reasons given to an applicant could change for no substantive cause.
- Problem statement. "Feature attributions used to explain credit decisions may be unstable across equally accurate models, which undermines their use as reasons for individual decisions."
- Research questions. How stable are SHAP attributions across retrained, equally accurate models on a public credit data set? Does an interpretable scoring model give more stable reasons at similar accuracy? How do credit analysts judge the two kinds of explanation on realistic cases?
- Design. Repeated retraining experiments with stability metrics; an interpretable baseline; a small study with practitioners.
The final version tests an assumption (Alvesson & Sandberg, 2011), compares post-hoc and interpretable approaches (Rudin, 2019; Lundberg & Lee, 2017), combines functional and human-centred evaluation (Ali et al., 2023), and connects to a legal requirement to explain individual decisions (European Parliament & Council of the European Union, 2024).
Before committing, check feasibility. A user study needs access to the people who would really use the explanations, such as clinicians, analysts or loan officers, and ethics approval to involve them. Experiments with large models need computing time; repeated retraining multiplies it. Public data sets make results comparable but may not reflect your target setting, while private data may limit what you can publish and share. If any of these is out of reach, narrow the question until it is not, for example by replacing a field study with a carefully designed online experiment.
Step 5: Plan what you will report
XAI results are hard to compare because studies report different things. Reproducibility checklists developed for machine learning research ask for code, data, hyperparameters and the computing setup (Pineau et al., 2021). For an XAI study, add the items below.
| Item | What to report |
|---|---|
| Model | Model type, training data, performance on held-out data, random seeds |
| Explanation method | Method, implementation and version, settings (for example, background data for SHAP) |
| Explained cases | How the explained instances were chosen; number of cases |
| Functional evaluation | Fidelity and stability metrics, with baselines such as random attributions |
| Human evaluation | Participants, task, conditions, outcome measures and ethics approval |
| Threat model | For security or privacy work: attacker knowledge and capabilities |
| Code and data | Repository, licence and any access restrictions |
Common mistakes
- Treating "apply method X to data set Y" as a research problem.
- Presenting post-hoc explanations as the model's true reasoning without testing faithfulness.
- Assuming an accuracy and interpretability trade-off instead of measuring it.
- Evaluating explanations only by visual appeal, or only with the research team as users.
- Ignoring the intended users, their decisions and their context.
- Reporting one random seed, so instability goes unnoticed.
Key takeaways
- XAI is crowded, so a doctoral problem should test an assumption rather than only fill a gap (Sandberg & Alvesson, 2011; Alvesson & Sandberg, 2011).
- Evaluating explanations, by computational tests and with users, is the central open problem (Ali et al., 2023).
- Post-hoc explanations approximate models; interpretable models are an alternative worth testing (Rudin, 2019; Lundberg & Lee, 2017; Ribeiro et al., 2016).
- Security, privacy and social context are legitimate XAI problem areas (Vassilev et al., 2025; Mittelstadt, 2019).
- Report models, methods, evaluation and code fully so that others can check your results (Pineau et al., 2021).